



Overview
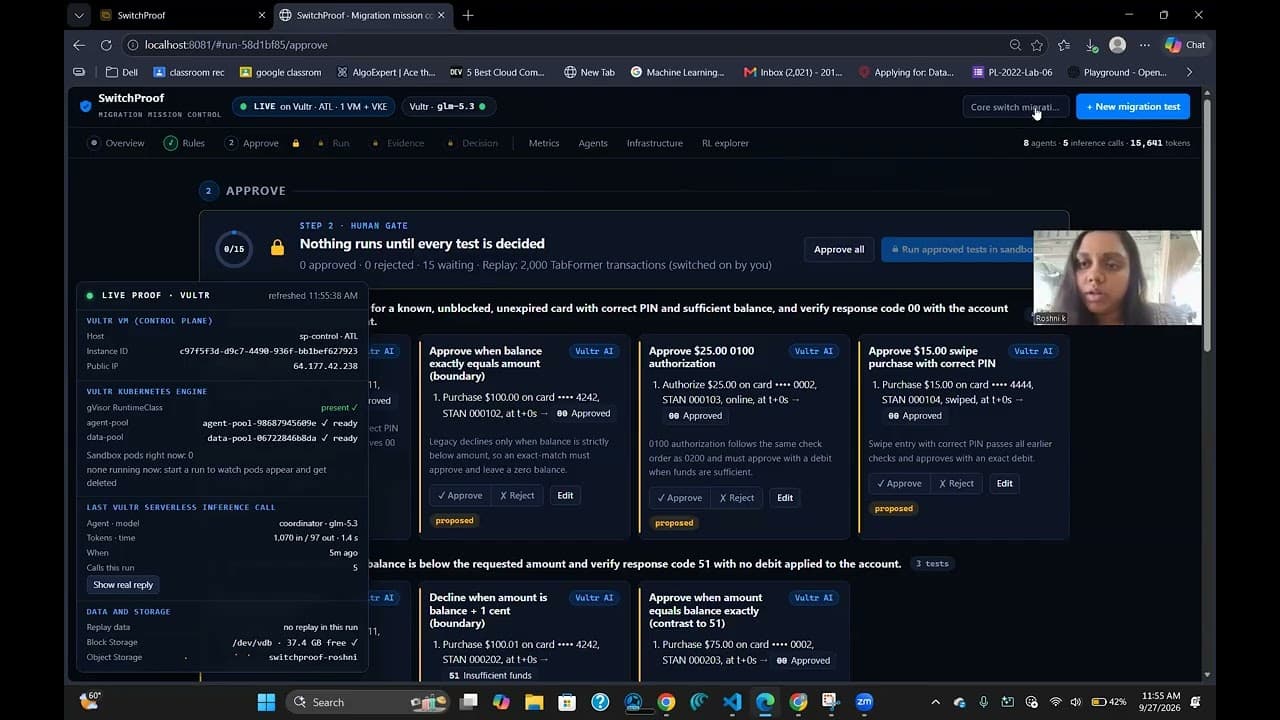
Bank payment migrations fail in public and expensive ways: TSB's 2018 migration cost about £81m in fines and compensation. SwitchProof is an AI test team for these migrations. A tester writes the payment rules in plain English. A coordinator agent on Vultr Serverless Inference (GLM-5.3) plans the work, and a generator agent (DeepSeek-v4.1-flash) writes ISO 8583 test cases. Nothing runs until the human approves every test. Approved tests, plus a 10,000-transaction replay of IBM's public synthetic TabFormer dataset, run in throwaway gVisor sandboxes on Vultr Kubernetes, in two isolated pools on separate VMs: agent-written tests and replay data never share a machine. When the new system misbehaves (in our demo a seeded bug charges customers twice), a triage agent designs its own follow-up tests to find the exact boundary, explains the root cause and the money at risk, and the human blocks or approves the release. A real run on Vultr: 10,022 tests in 42 sandboxes, 0 errors, defect found in 8.9 seconds, $0.04 of AI cost. An isolation probe inside a real sandbox shows rm -rf /, internet, cloud metadata and escape attempts all blocked. The payment switches are simulated and the defect is seeded; everything else runs live on Vultr.
Note: the demo URL is substituted with the GitHub repository link.
Tech stack
No comments yet
Be the first to comment on this project.
sentinel
Full-Stack Self-Healing DevOps & Security Copilot The Concept: An AI operations engineer that doesn't just suggest code fixes—it monitors cloud infra, detects uptime/security drops, automatically provisions fixes, and generates audit reports for enterprise compliance.
Agency Compiler
Agentic creative project compiler. Most creatives, agencies and designers dont know how to use ai, none the less agents. We created a platform that allows a creative agency or studio owner to instantly spin up agents based on the project ask, resources and scale.
ProofRun
ProofRun helps developers answer a critical question before shipping: will this update break behavior users rely on? An AI agent inspects two Git revisions, designs targeted experiments, and proposes repairs. An independent Docker-based verifier runs those experiments against both versions, preserves the original tests, and checks whether the repair actually works. Developers receive an update, skip, or postpone recommendation with recorded evidence and a reviewable patch. In a live synthetic…